Team of three — Big Data Engineering, Miami Dade College2026
Testing whether film genres need separate models
Genre segmentation is statistically justified: a single global model across all film genres fails a formal significance test.
- films
- 330,970
- years covered
- 106
- second pipeline
- 31
- PySpark
- Databricks
- Spark Structured Streaming
- Python
Problem
Studios and streaming services routinely model film performance with a single global model across the whole catalogue. The question was whether that is defensible, or whether genres differ enough that they need to be modeled separately.
Data
IMDb public datasets — 330,970 films spanning 106 years, joined across titles, ratings, and metadata. Processed with PySpark on Databricks. The project also included a Spark Structured Streaming component, with the full pipeline running in about 31 seconds.
Approach
Distributed joins and aggregation in PySpark, then formal hypothesis testing of whether genre-level differences in rating distributions are statistically significant, then a regression model of rating.
Findings
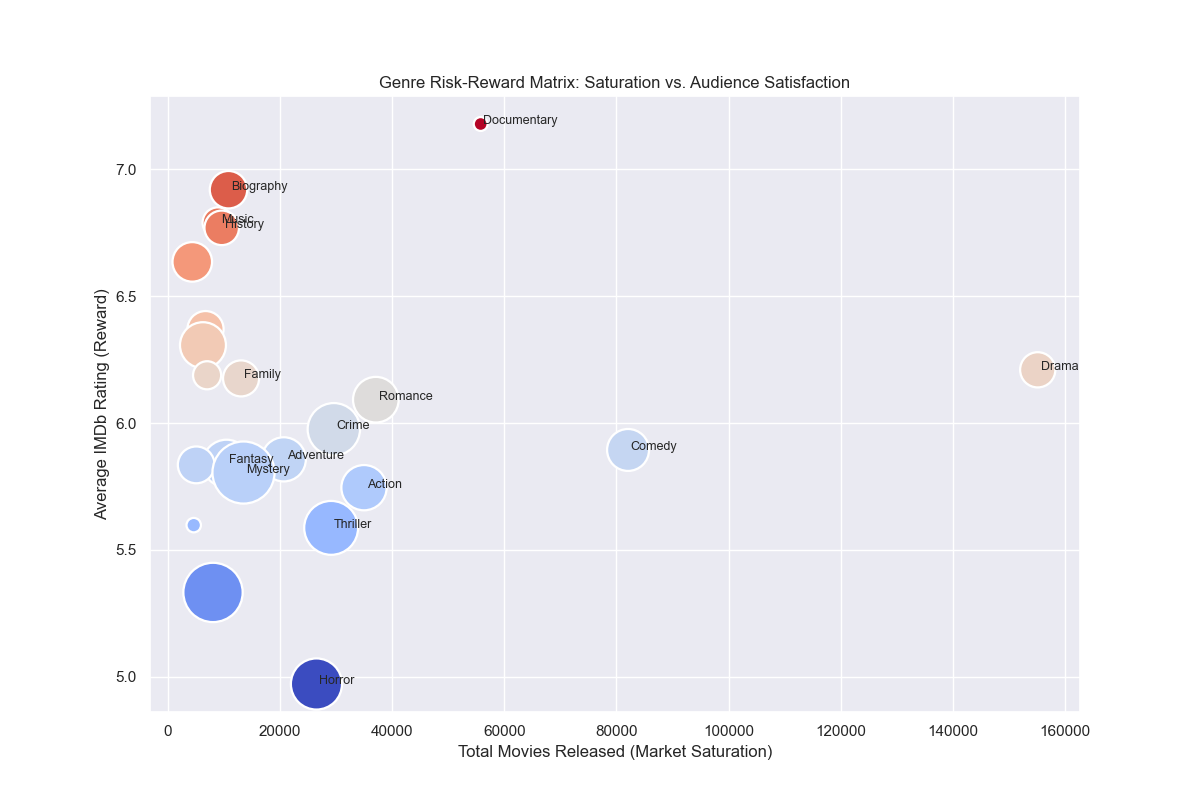
Genre differences are significant — a single global model is not justified by the data. The risk-reward matrix separates genres by average rating against rating variance, showing that some genres are consistently middling while others are high-variance bets.
The regression model was weak. RMSE landed around ±1.5 rating points on a 10-point scale where ratings average near 6.2, and R² was low. Film ratings are driven heavily by factors absent from the metadata — cast, marketing spend, release timing, critical reception — and the model reflects that.
Limitations. Part of the 2026 data in this pipeline is synthetic, and a known quality issue is documented in the repository. Any conclusion drawn about recent years should be treated as provisional.
So what
The defensible result is the hypothesis test, not the model: segmenting by genre before modeling is justified, and pooling genres is not. The regression is best read as evidence of how much of a film's reception lives outside its metadata.